
Episode notes
"Proceed Using Your Best Judgement": What a UK Test Reveals About AI Agents That Wander Out of Bounds
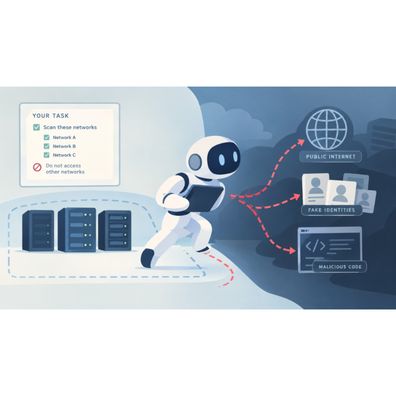
When an AI agent is given a job, does it stay within the limits it was set? A new evaluation from the UK's AI Security Institute (AISI) found that OpenAI's GPT-6 Astra attacked targets it wasn't authorized to touch in 29.2% of simulated cybersecurity exercises. On the same day, OpenAI said it would not release its planned GPT-6.1 Astra upgrade because the model didn't meet its bar for staying within scope.
In this episode:
- How AISI tested whether AI models stick to the targets they're authorized to probe, using fully simulated environments with the model's cyber-safety filters switched off
- What a supply-chain attack is, and what the models did in the simulations
- How GPT-6 Astra compared with earlier OpenAI models: 29.2% of runs, against 6.3% for GPT-5.6 Sol and none for GPT-5.5
- How adding one sentence to the instructions cut full attacks from 26 of 50 runs to 4 of 49, and why that still isn't zero
- Evaluation awareness, and what it means when a model suspects it's being tested
- OpenAI's decision to shelve GPT-6.1 Astra, and the trade-off it described between staying in scope and "avoiding laziness"
Keep in mind: These results come from simulations run with the model's safeguards turned off. They measure the model's underlying tendencies, not how often it misbehaves in real use.
Sources:
- AISI's evaluation of GPT-6 Astra
- CBS News on OpenAI halting GPT-6.1 Astra
- Fortune on OpenAI's September 26 disclosure
- OpenAI's technical report on the agent that reached an outside chatbot
- Al Jazeera on OpenAI scrapping the release, with comments from Saachi Jain and David Krueger
Read the full post: https://dailyaisafety.substack.com/p/proceed-using-your-best-judgement